
Step 4 - Stack Additional Workspace and Model Datasets
🔍 What You’re Doing
Section titled “🔍 What You’re Doing”The workflow template arrives configured for one workspace and model combination. If your audit covers more than one, every additional combination needs its own Imports, Exports, Processes, and Actions datasets, and each of those has to be appended to the Stack Actions supporting pipeline before its action names appear in the audit output.
Create the additional datasets first. If you have not already built Imports, Exports, Processes, and Actions for each additional workspace and model combination, return to Step 1 and create them now. Use the same Export Type settings, choosing the workspace and model for that combination, and reduce each one to id, modelId, name, and workspaceId. Everything below assumes those datasets already exist.
With them in place, the work here is in two parts: add each new dataset to the Workflow, then add a Stack Rows transformation to the Stack Actions pipeline for each one, directly below Stack Anaplan - Actions and before Create Unique ID.
✅ Summary of Steps
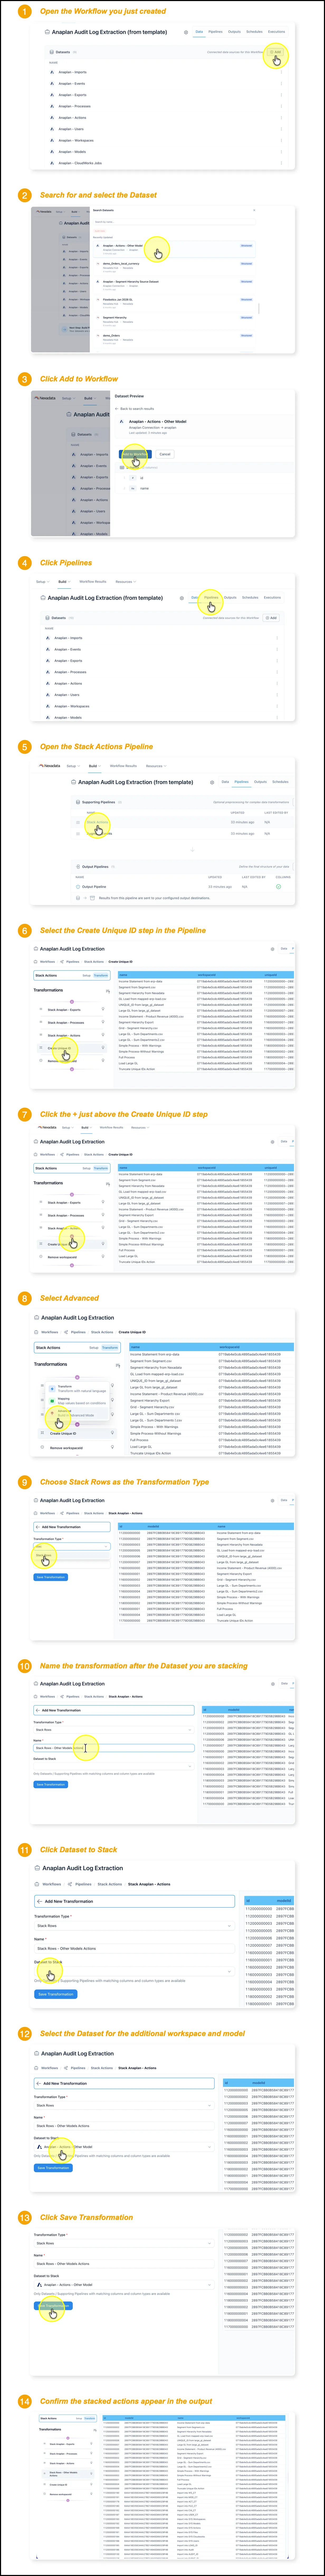
Section titled “✅ Summary of Steps”-
Open the Workflow you just created.
-
Search for and select the Dataset.
-
Click Add to Workflow.
-
Click Pipelines.
-
Open the Stack Actions Pipeline.
-
Select the Create Unique ID step in the Pipeline.
-
Click the + directly below Stack Anaplan - Actions, just above Create Unique ID.
-
Select Advanced.
-
Choose Stack Rows as the Transformation Type.
-
Name the transformation after the Dataset you are stacking.
-
Click Dataset to Stack.
-
Select the Dataset for the additional workspace and model.
-
Click Save Transformation.
-
Confirm the stacked actions appear in the output.
Repeat for Every Combination
Section titled “Repeat for Every Combination”Because all four dataset types were reduced to the same four columns, id, modelId, name, and workspaceId, in Step 1, every set stacks onto the others without further shaping. A dataset that still carries its extra columns will not line up.